
What the AI visibility checker measures
- Mention rate
- The share of answers that name your brand. Named in 2 of 6 answers = 33%.
- Recommendation position
- Where you appear in the numbered list an answer gives: 1st, 2nd, 3rd… The report keeps your best position.
- Competitors named instead
- Every brand listed above you, counted across all answers. The report shows the top 5.
- Citation
- Whether an AI answer links to your website as a source. A mention and a citation are different: an assistant can recommend a brand without linking to its site. The assistants answering this check don’t use web search, so their answers give no website citations.
What it does not measure: your visibility across all of AI search, how many real people see an answer, or your share of citations across the web. It measures mentions and positions in a small set of generated answers, which is why the score is a starting point, not a verdict.
What you get, and when
| What you see | When |
|---|---|
| Live progress: your category, then each question as it is asked | Free, no email |
| Score 0–100, whether you were named, your best position | On the page, after you enter your email |
| Mention rate per assistant, top 5 brands named instead, all 6 questions with a sample answer, fix list | In the report we email you, once |
| Your own prompts, asked weekly or more often, competitors over time | Paid Rankfender plans, from $89 a month |
Sample result: we checked rankfender.com
Current tool, 28 October 2026, 14:43 UTC. Category found: “all-in-one SEO and GEO platform”. Claude answered all 6 questions and Gemini 1 (Google quota), so 7 answers were scored. Score 2/100: named in 0 of 7. These are the 6 questions the checker wrote and the brands the first answer to each listed, in order.
| Question the checker asked | Rankfender named? | Listed instead, in order |
|---|---|---|
| best all-in-one SEO and GEO platform for tracking AI search citations | No | Semrush, Ahrefs, Similarweb |
| which tool combines SEO audits, keyword research and rank tracking with AI visibility monitoring | No | Semrush, Ahrefs, Moz Pro |
| top generative engine optimization tools for getting cited by ChatGPT and Perplexity | No | Semrush, Ahrefs, Similarweb |
| how to choose an SEO platform that also covers AI search engines | No | Semrush, Ahrefs, Similarweb, Moz Pro, BrightEdge |
| best SEO software with built-in AI content generation and backlink analysis | No | Semrush, Ahrefs, Surfer SEO, Moz Pro |
| recommended tools to optimize a website for both Google rankings and LLM citations | No | Semrush, Ahrefs |
Two lessons from our own result. First, a model answering from training data, with no web search, names the incumbents of the wider category: no dedicated AI-visibility tracker appeared, even for questions about AI citations. Second, the score is honest about a young brand. Our earlier check on 1 Oct 2026, answered by ChatGPT alone, gave the same 2/100. We publish ours because the method should hold for everyone, us included.
How the AI visibility checker works, step by step
Current tool, 28 October 2026. The checker uses one model to find your category and write the six questions, then sends those questions to the answer models. The two can differ; today Claude Haiku 5.5 does both. The steps, in order, with the same settings for every brand:
Find your category
We read your homepage title, meta description, Open Graph description and H1, then a model names your category in 3–6 words, the way a buyer would say it. A domain works better than a brand name: with a name alone, the model relies on what it already knows.
Write 6 buyer questions
The same model writes 6 non-branded questions a buyer in that category would ask, such as “best … for small businesses” or “how to choose …”. Your brand is never in the question, and years are removed so the questions stay evergreen.
Ask each assistant
Each question goes to Claude with one fixed instruction: answer with a numbered list of the most recommended options, one reason each. You see a live progress feed while the answers come back.
Read every answer
In each answer we look for your brand name, its position in the numbered list, and every brand listed above you. Those brands become your competitor list, counted across all answers.
Score and report
On the page: a 0–100 score, whether you were named and your best position. By email: each assistant’s mention rate, the top 5 brands named instead, all 6 questions with a sample answer, and a fix list.
The scoring formula
- Each answer scores 90 if you are named 1st, 75 2nd, 60 3rd, 48 4th, 35 5th or lower, and 30 if you are named outside a numbered list; +6 if the answer cites your site. Not named: 3.
- We average the answer scores and round that average to a whole number. Your score is 70% of that average plus 30% of the share of answers that name you, rounded to a whole number. This is how the checker’s code calculates it.
- The +6 citation bonus is added to an answer’s score before averaging, and needs an assistant with web search. The assistants answering today don’t search the web, so today the best answer scores 90 and the maximum score is 93 (0.7 × 90 + 30).
- Only answers that came back count. Claude answers all 6 questions, so at least 6 answers are scored; each Gemini answer that gets through adds one, up to 12. The report says how many answers each assistant gave.
- Example: named 2nd in 2 of 6 answers and absent from 4 gives (2 × 75 + 4 × 3) ÷ 6 = 27 average, so 0.7 × 27 + 0.3 × 33.3 = 28.9, rounded to 29.
Which models answer
| Step | Model | Web search | Status on 28 October 2026 |
|---|---|---|---|
| Category + 6 questions | GPT-4o (OpenAI); Claude Haiku 5.5 when OpenAI is unavailable | No | Claude Haiku 5.5 (OpenAI out of credit) |
| Answers | Claude Haiku 5.5 (Anthropic) | No | Answering every question |
| Answers | Gemini 2.5 Flash (Google) | No | When Google’s quota allows: 0–2 of 6 questions in our 3 checks |
| Answers | ChatGPT: gpt-4o-mini (OpenAI) | No | Paused (OpenAI credit); last answered 20 Oct 2026 |
| Answers | Perplexity Sonar | Yes | Paused; never answered a free check |
Paused assistants are skipped and left out of your report. Historical sample, 19 Jun – 20 Oct 2026 (146 visitor checks, our own tests excluded): ChatGPT answered all 146; Claude also answered 19 of them; Perplexity was tried once and returned nothing (Rankfender’s own data). Rankfender’s paid plans use a separate, larger set of assistants.
How to check your AI visibility by hand
You can repeat what the checker does in 20 minutes, with the apps your buyers use. It also shows you what the API cannot: answers with web search on.
Write 5–10 buyer questions
Questions a buyer asks before they know you: “best [category] for [use case]”, “[competitor] alternatives”, “how to choose a [category]”. Never include your brand.
Use a clean session
Log out or open a private window, so past chats and memory do not steer the answer. Note the country you are in.
Ask each assistant
Ask ChatGPT, Gemini, Claude, Perplexity and Copilot the same questions. Note whether web search ran; most apps show sources when it did.
Record three things
Are you named? In what position? Which brands and sources are named instead? A spreadsheet with one row per question and assistant is enough.
Repeat next month
Ask the same questions again. Change over time matters more than any single answer.
This is the same method as the free checker, with web search on. Use both: the checker for a quick, repeatable baseline; the manual check to see the sources assistants cite.
What your score means
The bands below come from the formula above. The share next to each band is how the 122 brands checked so far are spread (Rankfender’s own data, latest check per brand).
0–14 Not named
90% (110 of 122)
No answer names you (108 brands), or one does, low in a list (2). Most brands start here. Work on the third-party mentions and pages that assistants learn from.
15–39 Occasional
0%
Named in some answers, rarely near the top. Find which questions name you and which name competitors, and build pages for the gaps.
40–69 Often named
4% (5)
Named in many answers, at varying positions. Your aim now is position: become the first or second option named.
70–100 Default pick
6% (7)
Named in nearly every answer, often first. Typical for category leaders. Keep tracking: answers shift when models update.
In this sample, no brand landed in 15–39. That reflects these brands, questions, models and scoring rules, not a universal distribution of AI visibility: most of these brands were absent from every answer (score 2–3) or named in most of them. A brand named 2nd in 2 of 6 answers would score 29.
How to improve your score
Two factors influence AI visibility. Assistants answering without web search rely heavily on what they learned in training, along with the model’s current behaviour. Search-enabled assistants can also find and cite relevant pages from the web. The moves below can help; the impact varies by assistant, and they are not guaranteed to change your score immediately.
Get named where your category is discussed
Comparison articles, “best of” lists, review sites and forums in your niche. Independent mentions teach models that you belong in the answer.
Answer the buyer questions on your own site
One page per question from your report: a direct answer first, then detail, prices and comparisons. Assistants with web search quote pages like these.
Describe your brand the same way everywhere
Same name, category and one-line description on your site, directories and profiles. Add Organization schema. Consistency helps models tie mentions to you.
Let AI crawlers read your pages
Allow OAI-SearchBot, ChatGPT-User, Claude-SearchBot and PerplexityBot in robots.txt, and serve your content as HTML. Pages that relevant search crawlers can’t access are less likely to be discovered and cited by search-enabled assistants.
Measure again, on a schedule
Re-run the same questions monthly. Answers without web search change slowly, with model updates; answers with web search can pick up a new page once it is crawled.
Free AI visibility checkers tested: 13 tools, one brand
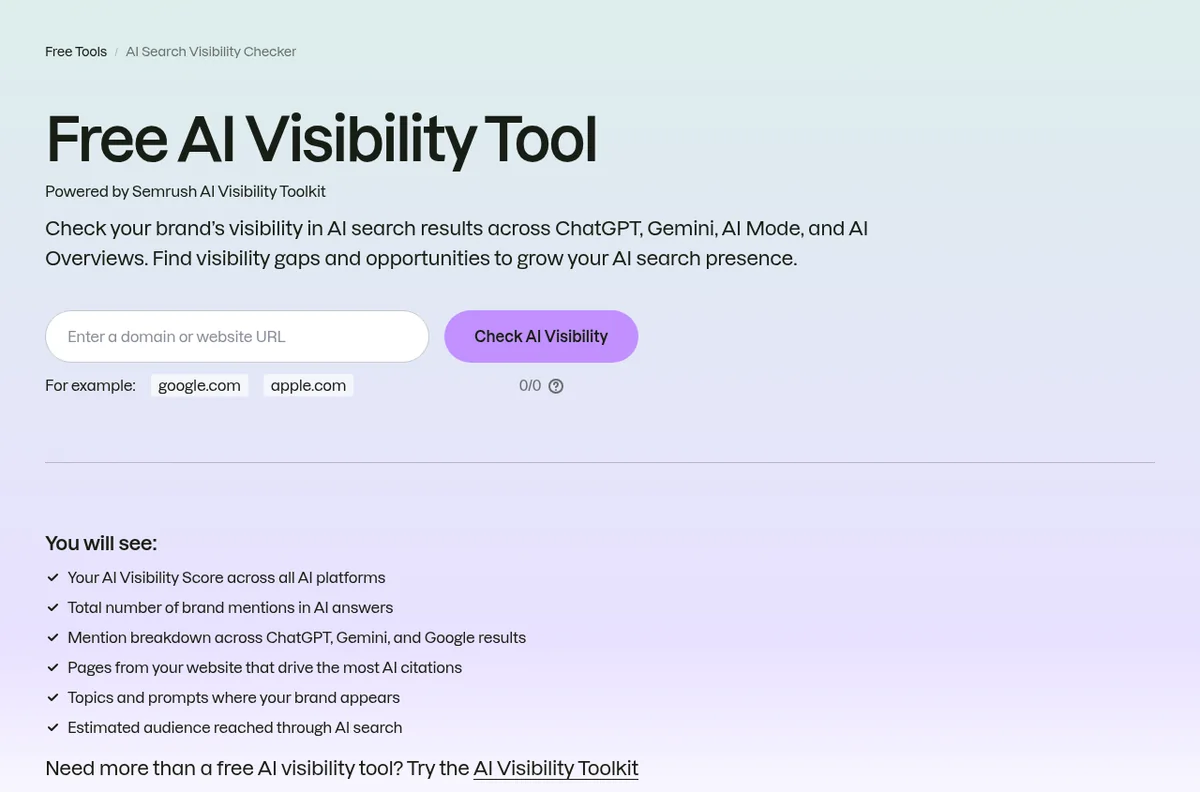
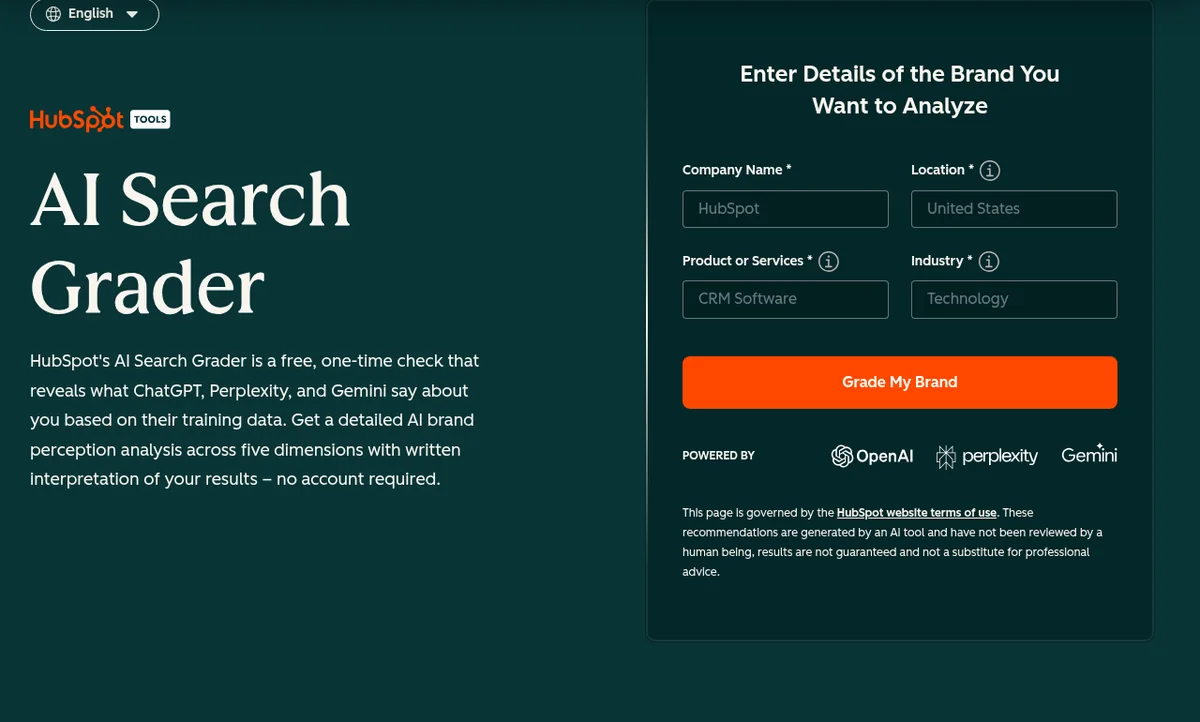
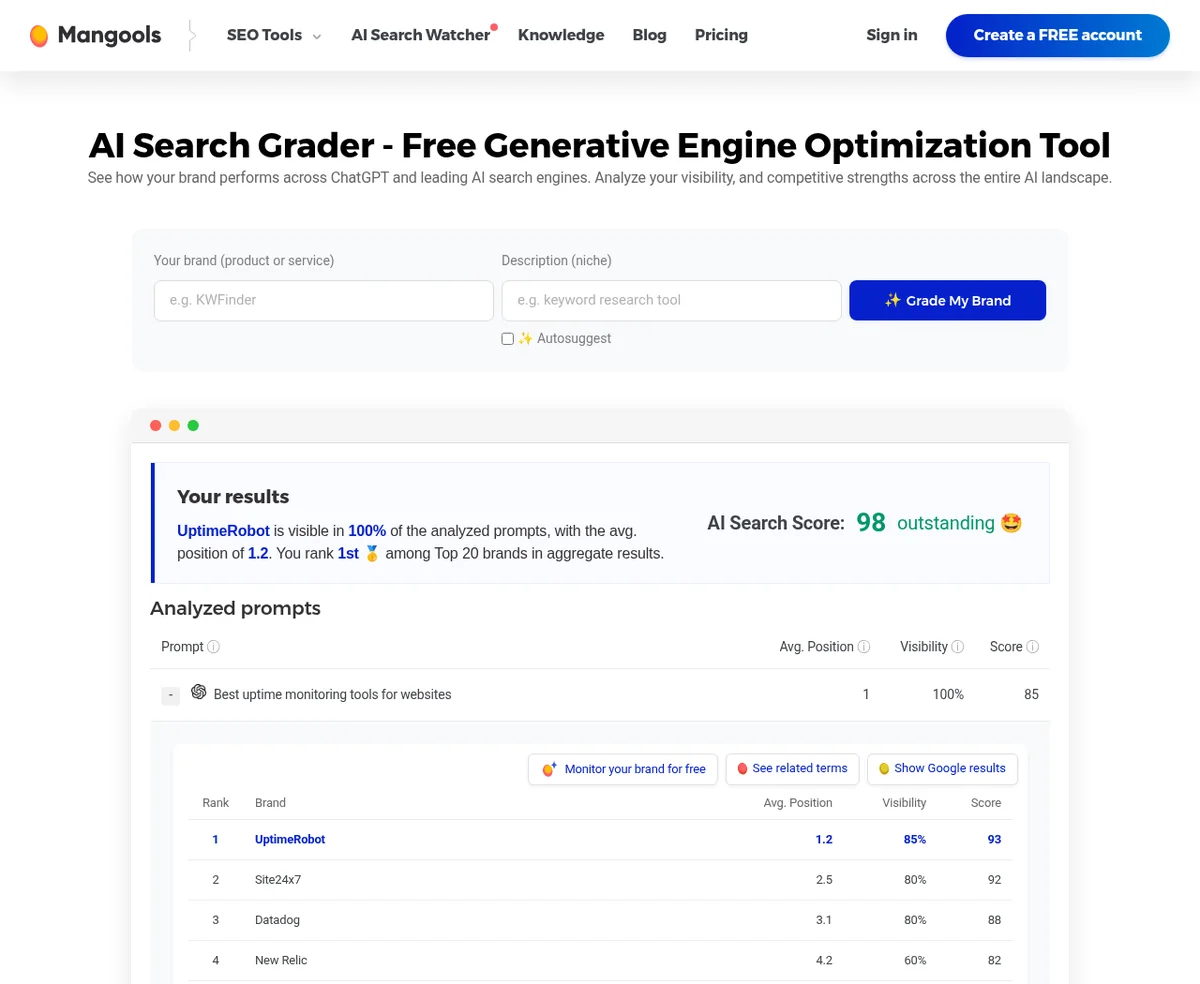
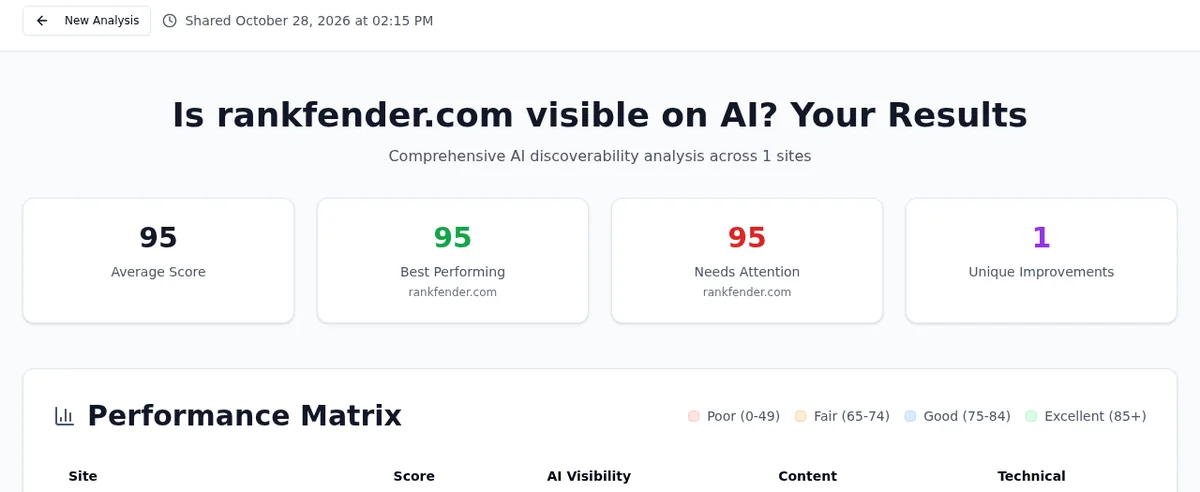
Competitor experiment, 28 October 2026. Free checkers measure three different things: some ask an AI live, some look your brand up in a stored database of past answers, and some scan your site without asking any AI. We opened 13 of them on 28 October 2026 from a US location, without an account or email, and recorded what each one really does.
| Checker | What it measures | AI assistants | Questions shown | Free without email | Email or form | Limit |
|---|---|---|---|---|---|---|
| Ahrefs | Stored database (Brand Radar), no live run | ChatGPT, Gemini, Perplexity, Copilot, AI Overviews, AI Mode (stated) | No | Mentions per assistant, 6-month trend, top 5 cited domains and pages | No; competitors need Brand Radar | None stated |
| Semrush | Stored database (26M+ prompts) | ChatGPT, AI Overviews; its FAQ lists Gemini and AI Mode as “coming soon” | No | 0–100 score, mentions, citations, competitors, 3-month trend | No | 3 a day |
| HubSpot AI Search Grader | Live, from training data | Page: GPT-5.4 mini, Perplexity, Gemini; the page code names newer versions | No | 0–100 score with published weights | Breakdown and PDF after email | One-time check |
| Mangools AI Search Grader | Live, API | GPT-5 Nano, Mistral Small 3.2, Llama 3.3 70B (3 more with a free account) | Yes | Score, visibility %, average position, brands per question | No | Limited (number not published) |
| Rankfender (this page) | Live, API, no web search | Claude; Gemini when its quota allows | Yes, in the report | Run and progress only | Score and report after email | 25 a day |
| Frase | Live | ChatGPT free; Perplexity and Gemini with a work email | 1 (its FAQ says 3) | ChatGPT result | Work email for 2 more assistants | Rate-limited |
| GoBIG | Live, with web search | Page: ChatGPT, Claude, Perplexity; we saw one Claude call with web search | Yes (5 local searches) | First of 5 searches | Name, email and US/CA phone for the rest | One use seen |
| SEOcrawl | AI estimate, “not a live measurement” | ChatGPT, Claude, Gemini, Perplexity (estimated) | 5 suggested | Score, likely mentions, competitors, PDF | No | 3 a day |
| Arobis | Site scan; asks no AI | None (readiness estimate per assistant) | No | Readiness score with weights, public report | Contact form for the fix plan | None stated |
| Am I Visible on AI | Site scan; asks no AI | None (robots.txt, schema, content) | No | Score with weights, share link | No | None stated |
| Amplitude | Live (emailed later) | ChatGPT, AI Overviews | In the report | Nothing | Work email first | None stated |
| Birdeye | Not visible without form | ChatGPT (its FAQ) | Not stated | Nothing | Name, email, phone first | 1 location |
| Otterly GEO Audit | Not visible without account | – | – | Nothing | Free account | – |
Tested on 28 October 2026; “stated” means as written on the vendor’s page. Backlinko’s checker (Semrush) and SEO Review Tools were read but not run (captcha). SE Ranking has no free checker; its ads lead to a 10-day trial of SE Visible.
Show the dated screenshots (4)
Paid trackers (verified 28 Oct 2026)
When one snapshot is not enough, a tracker asks your own prompts on a schedule. Here are the 12 trackers that free-checker pages push, from the cheapest entry plan up, checked on each vendor’s own pricing page on 28 October 2026. Prompts are the number of questions tracked; the same prompt is usually asked to every included assistant.
| Tracker | Entry plan, monthly (yearly) | Prompts | AI assistants | Updates | Trial · refund |
|---|---|---|---|---|---|
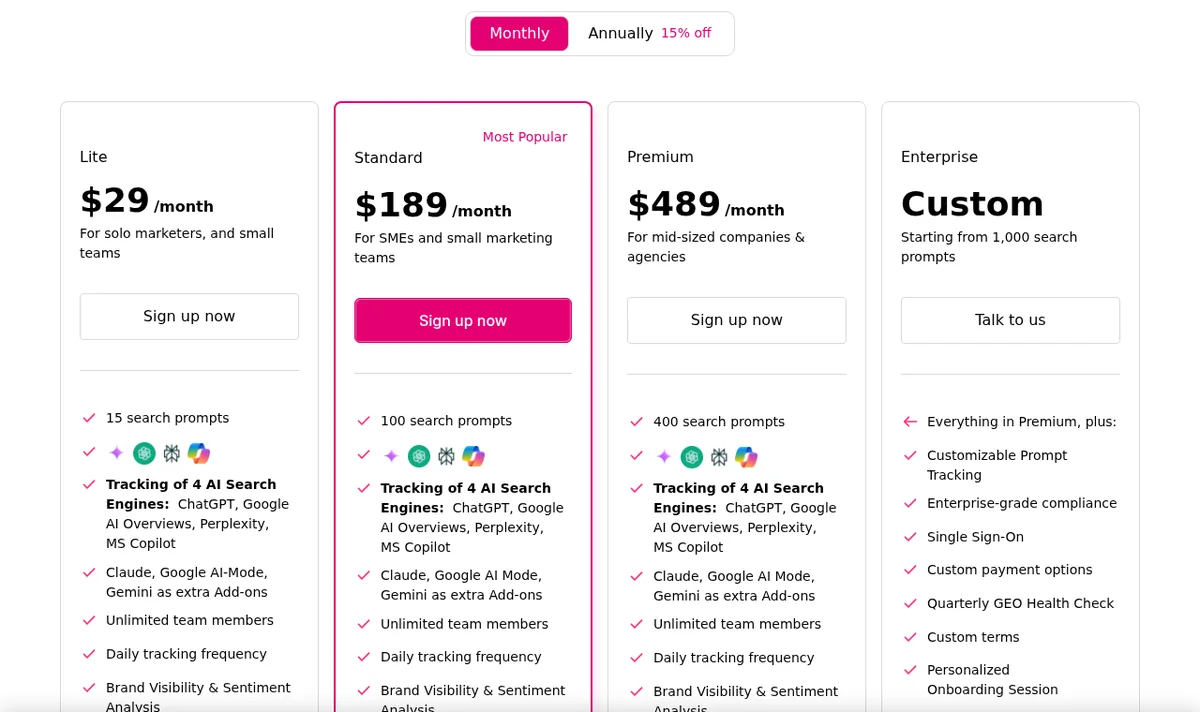
| Otterly.AI | Lite $29 ($25) | 15 | ChatGPT, AI Overviews, Perplexity, Copilot; Gemini or AI Mode +$9, Claude +$29 | Daily | 7 days, no card · no refund clause found |
| Frase | Starter $49 ($39) | 20 | ChatGPT, Google AI (Perplexity from $129, Claude and Gemini from $299) | Daily | 7 days, no card · none stated |
| Mangools AI Search Watcher | Pro $49 ($34.90) | 500 | ChatGPT, AI Overviews, AI Mode, Gemini, Claude, Grok, Mistral, Llama | Weekly | Free plan (5 prompts) · 48-hour refund |
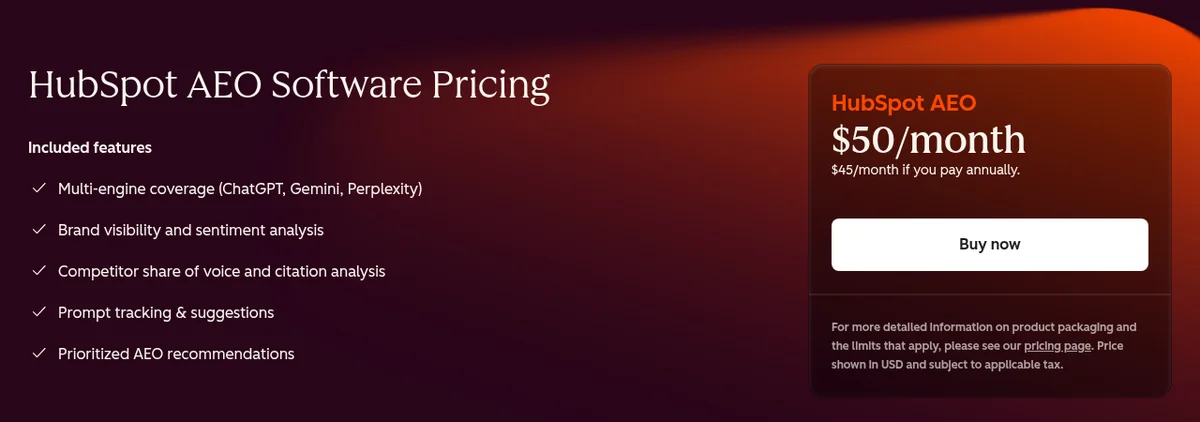
| HubSpot AEO | $50 ($45), beta | 25 | ChatGPT, Gemini, Perplexity | Daily | 25 prompts free, no card · none stated |
| SE Visible (SE Ranking) | Basic $89 ($71) | 75 | ChatGPT, AI Overviews, AI Mode, Gemini, Copilot | Daily | 10 days · SE Ranking: “payments are non-refundable” |
| Rankfender | Essential $89 ($73.83) | 15 | 5 on the plan; answering on 28 Oct 2026: Claude, Gemini, Mistral | Weekly | No trial · 14-day full refund |
| Peec AI | Starter $95 (15% off yearly) | 50 | 3 you choose from ChatGPT, AI Mode, AI Overviews, Copilot, Gemini, Naver | Daily | Trial (terms not shown) · no refund clause |
| Semrush AI Visibility Toolkit | $99 per user | 25 | Google AI Mode, ChatGPT (as named by Semrush) | Daily | No trial · no refunds on monthly plans |
| Ahrefs Brand Radar | In Lite $129 ($107.50) | 5 (150 checks a month) | AI Overviews, AI Mode, ChatGPT, Perplexity, Gemini, Copilot, Claude | Daily | No trial · “does not issue refunds in general” |
| Scrunch | Core $250 | 125 | ChatGPT, Perplexity, AI Overviews, Copilot | Not stated (5,000 answers a month) | 7 days · none stated |
| AthenaHQ | Starter $295 | Unlimited (3,600 answers a month) | 11, including Claude, Grok, DeepSeek, Mistral | Credit-based | Free tier · none stated |
| Profound | Enterprise, price on request | Free trial: 50 a day for 7 days | Trial: ChatGPT, Gemini, AI Overviews; Enterprise up to 9 | Daily | Free trial · contract |
Prices in US dollars as shown on each vendor’s US pricing page on 28 October 2026, before tax. “Yearly” is the monthly equivalent when billed yearly. Semrush One Starter ($199, 50 prompts) and Amplitude (AI visibility on its free plan, ChatGPT and AI Overviews) were also checked. Peec’s yearly price and Scrunch’s frequency are not published.
Show the dated screenshots (2)
Rankfender’s own data
Our data: what 122 brands’ checks show
Historical sample. 146 free checks run by visitors between 19 Jun and 20 Oct 2026, our own 16 tests excluded. ChatGPT answered all 146 (876 answers); Claude also answered 19 of them (114 answers): not today’s configuration. For brands checked more than once, only the latest check counts (122 brands). Aggregates only: no brand is named.
Key findings
89%
Most brands are not named at all
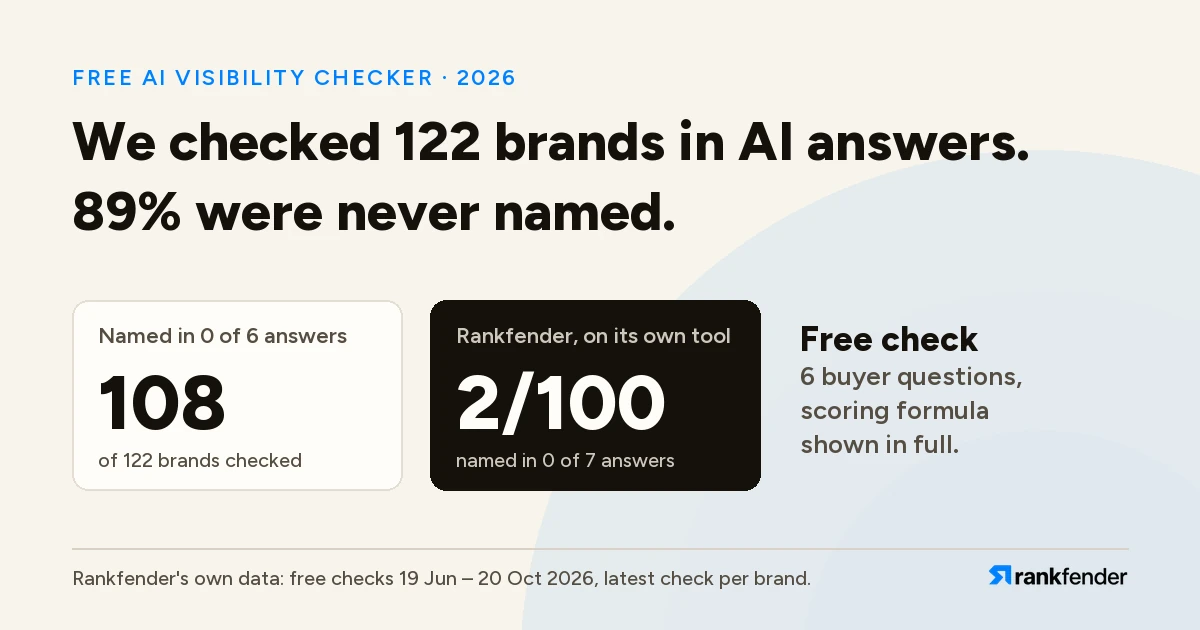
108 of 122 brands checked with this tool were named in none of their 6 answers (Rankfender’s own data, latest check per brand, 19 Jun – 20 Oct 2026). Median score: 2 out of 100. A low score is the normal starting point, not a fault in your site.
2/100
Including us
Rankfender ran its own domain through the current checker on 28 October 2026: named in 0 of 7 answers (6 from Claude, 1 from Gemini). Semrush and Ahrefs were named in all 7, Moz Pro in 5. See the questions and answers.
6 questions
Six questions, about 30 seconds
The current checker asks 6 buyer questions to Claude through its API: 6 answers per check, up to 12 when Gemini’s quota allows. The formula, the models and what is not measured are all on this page.
API ≠ app
What a free check cannot see
API answers have no web search, no memory and no location, so they can differ from what someone sees in the ChatGPT or Gemini app. Limits explains what that means for your score.
95 · 30 · 0/5
Free checkers disagree
The same site, rankfender.com, on the same day: 95/100 on a site-setup scanner, 30/100 on HubSpot’s grader, named in 0 of 5 GoBIG searches. Most free checkers don’t ask an AI live at all. 13 checkers compared.
- Never named (latest check per brand)89% (108 of 122)
Named in none of their 6 ChatGPT answers. Median score 2 out of 100.
- Named in every answer (latest check per brand)7% (9 of 122)
6 of them scored 70–100; 3 scored 40–69, named every time but lower in the lists.
- ChatGPT answers that named the brand (all 146 checks)9% (81 of 876)
gpt-4o-mini, 146 checks × 6 questions.
- Claude answers that named the brand (19 checks)11% (13 of 114)
Claude Haiku 4.5, the 19 checks it also answered, × 6. Small sample.
- Checks where an answer cited a source (all 146)0% (0 of 146)
API answers without web search cite nothing; only Perplexity returns sources, and it never answered.
Read it as a baseline, not a benchmark: visitors who run a free checker skew towards small and new brands. The pattern still matters. Assistants answering from memory repeat a short list of well-known names, so a new brand is usually absent rather than ranked low.
Limits: what a free check can’t tell you
Use the score to see whether you are in the answers at all and who is in your place. Do not use it as a precise measure. Here is why.
- API answers are not the app
- The checker calls each model’s API without web search, memory or location. In the app, OpenAI says ChatGPT may search the web, rewrites the question and uses saved memories and an approximate location, so a person may see a different answer. How much depends on the app and the features switched on.
- Answers vary between runs
- Ask the same question twice and the list can change. SparkToro’s 2,961-run study found under a 1-in-100 chance that two runs return the same list of brands. With 6 to 12 answers, one check can’t tell a 25% mention rate from a 50% one. Repeat checks over weeks.
- Six questions, written by a model
- The questions are generated for your category. They may not match the exact words your buyers use; check the list in your report.
- Brand-name matching
- We look for your brand name as written. Abbreviations, product names or misspellings in an answer are not counted.
- No sources yet
- Without web search the answers cite nothing, so the free check cannot show which pages assistants rely on.
- A snapshot, not tracking
- For weekly or daily answers from more assistants, with your own prompts, you need a tracker. Paid trackers compared.
How we researched this page
Disclosure: We make Rankfender and this checker. The other free checkers were tested on their public pages on 28 Oct 2026 without paid accounts, and paid-tracker prices come from each vendor’s own pricing page that day. No affiliate links.
- Our tool: the checker’s source code was read on 28 October 2026 (category step, prompts, scoring, models). The formula on this page is that code.
- Claims gate: a live check was run on 28 October 2026; only assistants that answered it are named.
- Our data: Rankfender’s own data, from the checks stored by this tool between 19 Jun and 20 Oct 2026: aggregates only, our own tests excluded, latest check per brand.
- Other checkers: each free tool was opened on 28 Oct 2026 from a US location, with dated screenshots. We did not enter an email or create an account; where a tool needs one, the table says so.
- Paid trackers: prices, prompts, assistants and update frequency from each vendor’s own pricing page on 28 Oct 2026, in US dollars.
Evidence
What each claim on this page rests on.
| Claim | Source | Date |
|---|---|---|
| Scoring formula, models, 6 questions | Checker source (supabase/functions/ai-visibility-check) | 28 October 2026 |
| 122 brands, 89% never named | Rankfender’s own data: 162 stored checks − 16 own tests = 146; latest check per brand = 122 | 19 Jun – 20 Oct 2026 |
| Rankfender 2/100 | Rankfender’s own data: live check of rankfender.com, current tool (also 2/100 on 1 Oct with ChatGPT) | 28 October 2026 |
| Assistants named for the free check | Live check + prod answer log (claims gate) | 28 October 2026 |
| 13 free checkers | Hands-on test, US location, no account or email; dated screenshots | 28 October 2026 |
| 12 paid trackers, USD | Each vendor’s own pricing page, US view; dated screenshots | 28 October 2026 |
| Run-to-run variance | SparkToro study, 2,961 runs | 28 Jan 2026 |